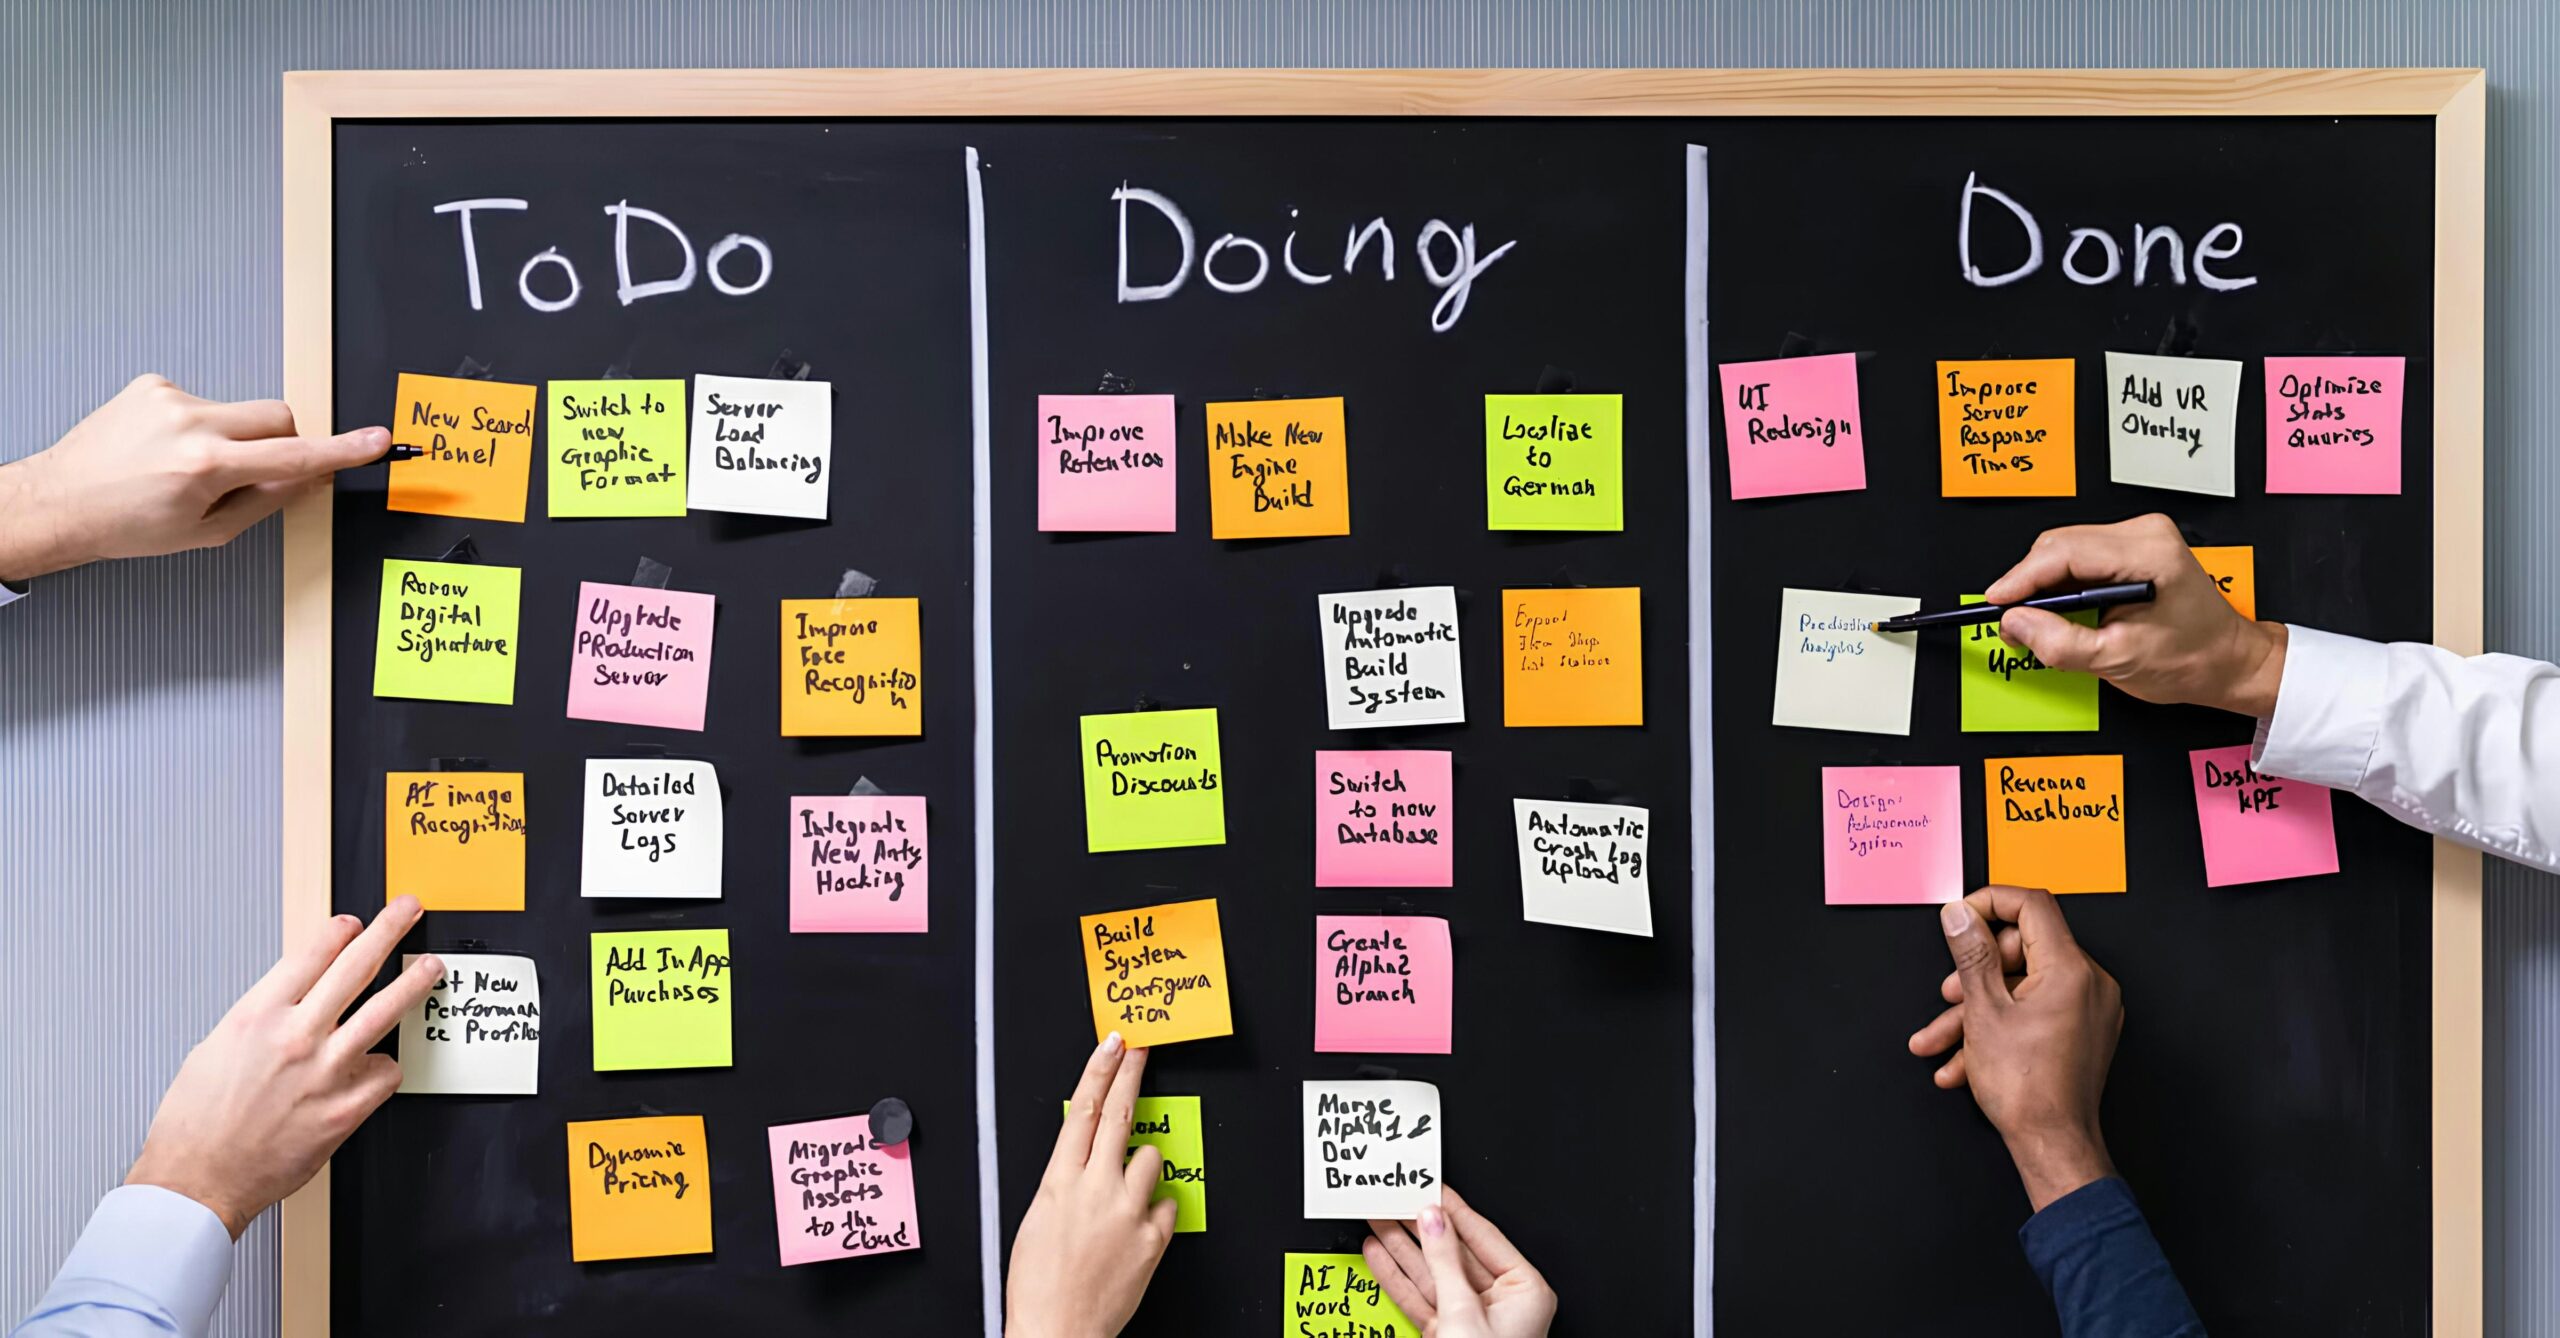
In complex operational environments, projects rarely execute with absolute perfection. Software deployments encounter unexpected outages, product launches face supply chain bottlenecks, and marketing campaigns experience technical friction. The difference between high-performing organizations and those caught in cycles of repeated failure lies in their reflective capability. Learning how to run an effective post mortem meeting provides teams with a systematic method to analyze project outcomes, diagnose systemic root causes, and embed institutional learning into future workflows.
When properly designed, a post-mortem session transforms subjective frustration into objective operational intelligence. Conversely, poorly executed reviews degenerate into finger-pointing sessions that damage psychological safety while failing to address underlying systemic vulnerabilities. Mastering how to run an effective post-mortem meeting requires balancing psychological safety, rigorous root-cause analysis, and practical action-item governance.
Background and Foundational Concepts
The term “post-mortem” originates in medicine, referring to an examination conducted after death to determine the exact cause of mortality. In engineering, software development, and project management, the concept was adapted to evaluate completed projects, critical incidents, or major operational milestones.
While agile frameworks often use terms like “retrospective” or “lessons learned session,” subtle distinctions separate these reflection formats:
| Format Type | Primary Focus | Trigger / Timing | Typical Scope |
| Retrospective | Team process & sprint health | Recurring cadence (e.g., bi-weekly) | Continuous team development |
| Post-Mortem Meeting | Specific event, launch, or failure | Incident resolution or project end | Systems, architecture, & root causes |
| After-Action Review (AAR) | Operational execution vs. plan | Immediate completion of a mission | Tactical tactical adjustments |
Knowing how to run an effective post-mortem meeting requires understanding that its purpose extends beyond recording what went wrong. A comprehensive review analyzes both successes and failures to evaluate how decisions were made under uncertainty and apply project management best practices to future workflows.
Core Principles of Effective Post-Mortem Reviews
To extract maximum value from a project debrief, organizations must ground their review process in three core structural principles.
1. The Blameless Post-Mortem Culture
Pioneered in high-reliability organizations and popularized by modern site reliability engineering (SRE) practices, the blameless post-mortem rests on a crucial premise: human error is the symptom of a deeper systemic failure, not the root cause.
If an engineer deploys faulty code that breaks a production server, blaming the individual ignores the systemic gaps that permitted the error:
- Why did automated tests fail to catch the bug?
- Why did the deployment pipeline permit unverified code into production?
- Why were rollback mechanisms slow or poorly documented?
When teams understand how to run an effective post-mortem meeting under blameless principles, participants speak openly about mistakes without fear of professional reprisal. If psychological safety is lacking, team members hide errors, distort timelines, and deflect accountability, destroying the objective data required for systemic repair.
2. Fact-Based Timeline Reconstruction
Human memory degrades rapidly under stress. Effective debriefs rely on objective, chronological timelines compiled from telemetry logs, timestamped communication channels, incident management records, version control histories, and ticket management systems. Reconstructing a precise sequence of events establishes a shared ground truth before participants attempt to diagnose causes.
3. Focus on Systemic Resilience
Fixing human behavior through admonitions to “be more careful” is ineffective. Systemic engineering focuses on safeguards, automation, process redesign, and structural redundancy. An effective session shifts the focus from individual performance to system design.
Current Understanding: Psychological Safety and Root Cause Analysis
Understanding how to run an effective post-mortem meeting requires mastering root cause analysis tools that bypass surface-level assumptions.
[ Incident or Project Milestone ]
│
▼
[ Fact-Based Timeline Assembly ]
│
▼
[ Root Cause Analysis (5 Whys / Fishbone) ]
│
▼
┌───────────────────────┴───────────────────────┐
▼ ▼
[ Systemic Safeguards ] [ Process Redesign ]
(Automation, Tests, Checks) (SOPs, Communication)
│ │
└───────────────────────┬───────────────────────┘
│
▼
[ Actionable Tracking ]
The 5 Whys Methodology
Developed within the Toyota Production System, the 5 Whys technique iteratively drills down through layers of cause and effect.
- Problem Statement: The customer database went offline for 45 minutes during peak hours.
- Why did the database go offline? It ran out of disk space due to an uncompressed log file expansion.
- Why did the log file expand uncontrollably? A debugging mode was left enabled after the previous software release.
- Why was debugging mode left enabled? The deployment checklist relied on manual verification steps.
- Why were manual steps used instead of automated checks? The deployment script lacked pre-flight validation rules.
- Why lacked validation rules? System architecture guidelines had not prioritized automated deployment guards during initial design.
By moving from a surface-level error (log file expansion) to a systemic root cause (missing automated deployment guards), the team identifies a long-term solution rather than a temporary patch.
The Ishkawa (Fishbone) Diagram
For multi-faceted operational failures, the Fishbone diagram categorizes potential causes across six domains, providing a practical root cause analysis framework for identifying systemic issues.
- People: Training, staffing levels, role clarity.
- Process: Standard operating procedures, handoff protocols, review gates.
- Technology: Infrastructure, tools, software architecture.
- Environment: Market conditions, regulatory changes, remote work barriers.
- Materials/Data: Third-party APIs, vendor inputs, dataset integrity.
- Management: Resource allocation, timeline expectations, strategic prioritization.
Step-by-Step Implementation Framework
Knowing how to run an effective post-mortem meeting in practice demands a structured, reproducible framework divided into three distinct phases.
┌─────────────────────────────────────────────────────────────────────────┐
│ PRE-MEETING PREPARATION │
│ • Appoint neutral facilitator & scribe │
│ • Gather objective logs, telemetry, & ticket histories │
│ • Draft initial chronological timeline │
└────────────────────────────────────┬────────────────────────────────────┘
│
▼
┌─────────────────────────────────────────────────────────────────────────┐
│ MEETING EXECUTION (60 Min) │
│ • Establish blameless ground rules (5 min) │
│ • Validate timeline against objective evidence (15 min) │
│ • Conduct 5 Whys root cause analysis (25 min) │
│ • Formulate SMART action items with dedicated owners (15 min) │
└────────────────────────────────────┬────────────────────────────────────┘
│
▼
┌─────────────────────────────────────────────────────────────────────────┐
│ POST-MEETING GOVERNANCE │
│ • Publish structured post-mortem document │
│ • Log action items in primary issue tracker │
│ • Audit completion rates during leadership reviews │
└─────────────────────────────────────────────────────────────────────────┘
1.Phase 1: Pre-Meeting Preparation:Establish roles, collect data, and build an objective timeline.
Before gathering the team, appoint a neutral facilitator and a designated scribe. Collect all relevant operational data, monitoring charts, communication logs, and pull requests. Draft a raw chronological timeline so meeting time is spent analyzing causes rather than debating basic facts.
2.Phase 2: Meeting Facilitation:Set psychological safety, validate facts, and conduct root cause analysis.
Begin the session by explicitly stating the blameless principle. Review and refine the timeline as a group. Transition to root cause analysis using the 5 Whys framework to identify systemic vulnerabilities rather than personal errors.
3.Phase 3: Action Item Generation:Convert findings into SMART action items with clear ownership.
Synthesize discussion insights into specific, measurable, achievable, relevant, and time-bound (SMART) tasks. Assign each action item to a single named owner rather than a broad team, and integrate these tasks directly into the primary engineering or project backlog.
4.Phase 4: Post-Meeting Follow-Up:Publish findings and track corrective measures through to completion.
Distribute the finalized post-mortem document across the broader organization to promote cross-team learning. Review outstanding action items during regular operational reviews to ensure preventative measures are completed.
Important Considerations and Practical Examples
To understand how to run an effective post-mortem meeting across varying organizational structures, consider how different departments adapt these principles.
Software Engineering vs. Marketing Campaigns
While software engineering post-mortems center on system uptime, error budgets, and architecture, non-technical teams gain equal value from the format.
- E-Commerce Product Launch: If a retail brand experiences inventory stockouts within two hours of a holiday campaign launch, a post-mortem evaluates demand-forecasting models, supplier lead times, and site load capacity.
- Corporate Event Execution: If a major hybrid conference suffers audio-visual failures during a keynote, the debrief examines AV vendor contract clauses, redundancy testing protocols, and emergency escalation pathways.
Key Roles and Responsibilities
To maintain momentum and neutrality during the session, assign clear functional responsibilities:
- The Facilitator: Guides the conversation, enforces blameless communication, keeps time, and ensures deep root cause exploration.
- The Scribe: Captures key insights, records timeline additions, and documents action items in real time.
- Subject Matter Experts (SMEs): Provide technical context, explain operational decisions, and evaluate proposed remediation steps.
Potential Problems and Common Pitfalls
Even well-intentioned teams encounter friction when learning how to run an effective post-mortem meeting. Recognizing these common anti-patterns preserves the integrity of the process.
1. The “Witch Hunt” Trap
When leadership uses post-mortems to assign personal fault or justify punitive measures, the meeting morphs into a defensive confrontation. Team members construct evasive narratives, withholding critical operational facts. Leaders must reinforce that the primary objective is understanding how a system permitted a failure, not who committed an error.
2. Action Item Overload
A common error is generating dozens of superficial recommendations that swamp the team’s operational backlog. Focus on 3 to 5 high-impact, systemic modifications that prevent recurrence.
[ Unfocused Post-Mortem Output ] ──> 25 Minor Tasks ──> Backlog Stagnation ──> Recurrent Failures
VS.
[ Effective Post-Mortem Output ] ──> 3 High-Impact Fixes ──> Systemic Remediation ──> Long-term Uptime
3. The “File and Forget” Syndrome
Publishing a comprehensive post-mortem document that sits unread in an internal wiki creates a false sense of accomplishment. Without tracking action items through regular sprint planning, the meeting becomes performative, and identical operational failures recur over time.
Recommended Practices for Sustained Success
To institutionalize how to run an effective post-mortem meeting as a competitive operational advantage, incorporate these advanced practices:
- Establish Clear Severity Thresholds: Not every minor hiccup warrants a 60-minute meeting. Define clear criteria (e.g., outages exceeding 15 minutes, financial impact over $10,000, or launch delays beyond 48 hours) to trigger a formal post-mortem.
- Standardize Page Templates: Use a unified post-mortem template across all departments. Standardized headers—such as Executive Summary, Incident Timeline, Root Cause Analysis, What Went Well, What Went Poorly, and Action Items—ensure consistency and facilitate cross-team audits.
- Institute a “Post-Mortem of Post-Mortems”: Periodically audit past reviews to evaluate action item completion rates and verify whether preventative measures successfully mitigated recurring incidents.
Final Analysis and Strategic Value
Mastering how to run an effective post-mortem meeting transforms operational friction into organizational growth. High-reliability organizations treat unexpected failures not as embarrassing setbacks, but as valuable operational data paid for in real time. By establishing blameless psychological safety, conducting rigorous root cause investigations, and holding teams accountable for systemic repairs, organizations build resilient processes that scale smoothly alongside commercial growth.
Frequently Asked Questions (FAQs)
1. What is the ideal time frame to hold a post-mortem meeting after an incident?
A post-mortem meeting should ideally take place within 24 to 48 hours after an incident is resolved or a project phase concludes. Conducting the session quickly ensures that details remain fresh in participants’ minds while providing enough time to compile objective logs and telemetry data.
2. How does a post-mortem differ from a sprint retrospective?
A sprint retrospective focuses on broad team dynamics, process efficiency, and continuous velocity across a regular time interval (such as a bi-weekly sprint). A post-mortem focuses on analyzing a specific, distinct event, major project outcome, or system failure to uncover technical and procedural root causes.
3. Who should attend a post-mortem meeting?
Attendance should include the core team members directly involved in the project or incident, the neutral facilitator, a scribe, and key cross-functional stakeholders impacted by the outcome (such as customer support leads or product managers). Keep the group focused to maintain productive conversation.
4. How do you maintain a blameless culture if someone made a negligent mistake?
Maintaining a blameless culture requires separating system design from personal intent. Even in cases of human error, the analytical focus must remain on why the system lacked safeguards, verification checks, or training protocols that could have prevented or mitigated the mistake.
5. What should you do if team members are hesitant to speak up during the meeting?
If team members are reluctant to share insights, use structured, low-friction input methods. Have participants submit anonymous written thoughts or populate a shared digital whiteboard prior to the meeting. The facilitator should also explicitly model blameless language and open the session by validating psychological safety.